Experience across confidential AI-data programs
Client identities withheld due to confidentiality obligations. Categories shown are illustrative of engagement types, not specific organizations.
From human demonstration
to machine action.
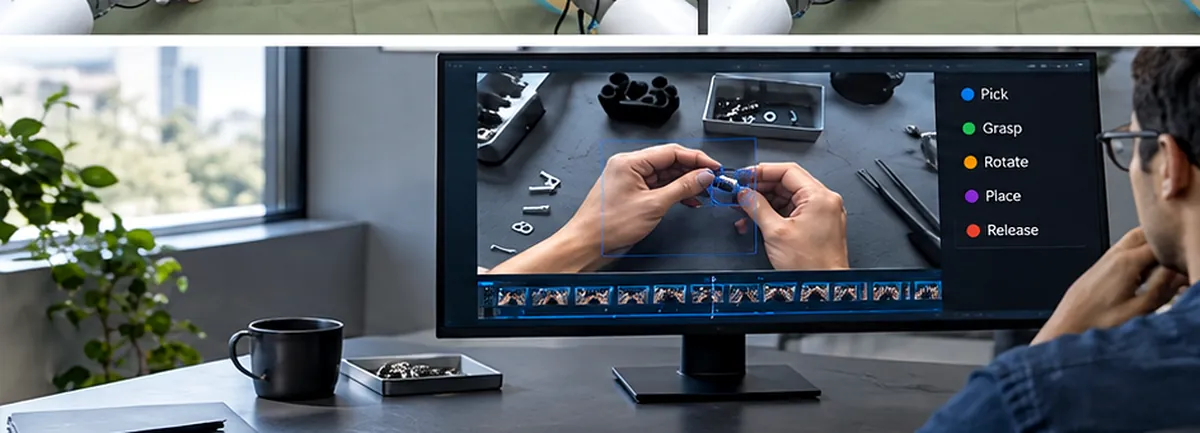
Real-world tasks contain more than motion. They contain intent, contact, sequence and change. We turn human demonstrations into reviewed, structured data for physical-AI and robotics learning programs.
Egocentric & robotics data,
operated with human judgment.
First-person collection, action segmentation, temporal boundaries and hand-object interaction labels. Connected to instructions, captions and clear completion criteria.
Scoped collection protocols. Calibrated annotators. Review and adjudication before delivery.
Explore Physical AI & Egocentric Data- 01Human demonstrationTask, objects and intent
- 02Egocentric captureApproved recording protocol
- 03Action segmentationSteps and temporal boundaries
- 04Interaction labelsHands, objects and state
- 05Instruction alignmentCaptions and intended result
- 06QA & adjudicationConsistency and edge cases
- 07Structured training dataVersioned, agreed schema
The workforce behind better AI — operated as a program, not a headcount.
Frontier models are only as good as the human judgment that shapes them. We don’t hand you a pool of annotators and wish you luck. We stand up a qualified, calibrated, measured operation around your objective — and run it.
“Here are some annotators. Write your own guidelines, manage quality yourself, and hope the labels are consistent.”
We manufacture reliable human judgment at scale: people + qualification + workflow + measurement + security — delivered as a managed data program.
Train. Evaluate. Improve — at scale.
Data for post-training
Expert responses, SFT data, preference pairs, critiques and rewrites that teach models what “good” looks like.
Human evaluation
Rubric scoring, pairwise comparison, factuality and agent-trajectory review to measure real model quality.
Feedback loops
Error patterns and disagreements feed back into guidelines, taxonomies and worker coaching — every cycle.
Managed scale
Recruit, qualify and calibrate large specialist teams — then hold quality steady as volume grows.
Human data across the whole model lifecycle.
Generative AI & LLM Post-Training
SFT data, response creation, preference ranking, critique, rewriting and reasoning data for RLHF/DPO workflows.
ExploreModel & Agent Evaluation
Rubric-based scoring, pairwise comparison, factuality and groundedness, plus agent and tool-use trajectory review.
ExploreAI Safety & Red Teaming
Policy evaluation, adversarial prompting, jailbreak testing, safety categorization and culturally-aware review.
ExploreMultimodal Data
Annotation and evaluation across text, images, video, audio, speech and documents — with domain specialists.
ExploreData Collection & Curation
Expert-created data, multilingual collection, source validation and structured dataset curation and cleanup.
ExploreTrust & Safety Operations
Content moderation, policy classification, integrity labeling, abuse taxonomies, escalation and adjudication.
ExploreA managed operating model — not a labeling queue.
Every program runs the same disciplined lifecycle, so quality is engineered in from the first pilot to steady-state production.
Quality you can audit — not adjectives.
We treat quality as a measured system. Work flows through layered review and senior adjudication before it reaches you, and we report the signals that actually predict downstream model behavior.
- Gold tasks & hidden checks embedded in production
- Inter-annotator agreement & reviewer calibration
- Adjudication for disagreement & critical errors
- Per-batch acceptance, rework and turnaround SLAs
Specialists become production-ready through a system — not a sign-up form.
Fifteen years of operations taught us how to source, qualify and hold a large distributed workforce to a standard. That system is our real product.
Specialist roles we qualify
Built for confidential model data.
Frontier data is sensitive. Programs run inside controlled, access-managed environments — and, where required, directly in your systems — so confidential prompts, responses and evaluations stay protected end to end.
- Role-based access, MFA and least-privilege controls
- Client-controlled environments & VDI where contracted
- Workforce NDAs, logging and monitored access
- Defined retention, deletion and off-boarding
Security controls designed with reference to ISO/IEC 27001 & SOC 2 Trust Services Criteria.
Visit the Trust CenterPrograms, not promises.
Representative engagements, written to be procurement evidence. Client identities and any confidential metrics are withheld under NDA.
Multimodal evaluation at pace
Coding & STEM expert evaluation
Domain depth and multilingual reach.
Human data is only as good as the humans behind it. We qualify contributors for the domain and the language — and for cultural context, which is where generic crowds fail.
How we qualify expertsDomains
Language & cultural coverage
The advantage nobody can spin up overnight.
OmniTech grew up running large, secure, 24/7 operations — recruitment, training, scheduling, QA and delivery at scale. AI-data work rewards exactly that muscle: the hard part isn’t labeling one example, it’s running thousands of qualified people to a consistent standard.
Workforce management
Recruiting, scheduling and coaching large distributed teams.
Process discipline
Repeatable delivery, SLAs and quality control as standard.
Secure delivery
Access control and confidentiality built into operations.
Let’s build better AI data together.
Tell us what you’re training or evaluating. We’ll scope a pilot, define the quality bar, and stand up a qualified team behind it.


